Building a Brand Signal Stack for the AI Search Era
A three-layer framework for getting AI assistants to recommend your brand.
A perception intelligence platform for AI era brands should measure how assistants represent a brand. Building a brand signal stack means making it easy for AI systems to find, understand, and confidently recommend that brand through the sources they read. The goal is to connect AI visibility and accuracy with traditional reputation measures, rather than mistake search rankings for the whole picture.
How AI search selects brands to cite, and why page-level optimization no longer controls the outcome
Rankings can hold steady while leads decline. That is the dissonance AI search creates for teams whose dashboards still look reassuringly green. A brand can retain its place in search results yet lose its place in the answer a customer actually reads. Birdeye’s State of AI Search 2026 explains that ChatGPT, Gemini, and Perplexity generate responses by selecting and validating a small set of trusted sources. Being in that response helps decide which brands the customer will consider.
Brands must therefore move from winning a ranked position to earning a trusted recommendation. AI systems evaluate accuracy, relevance, trust, and consistency across surfaces, so crawlability and keyword density alone cannot settle the outcome. AYSA’s 2026 brand signals framework describes how one prompt can compress discovery, evaluation, and selection into a single interaction. The assistant does the tab-opening on the customer’s behalf. Because its answer draws on the wider web, polishing a landing page cannot repair a trust deficit in reviews, directories, and third-party coverage.
What "brand signal stack" means and the three jobs every brand must do to be recommended
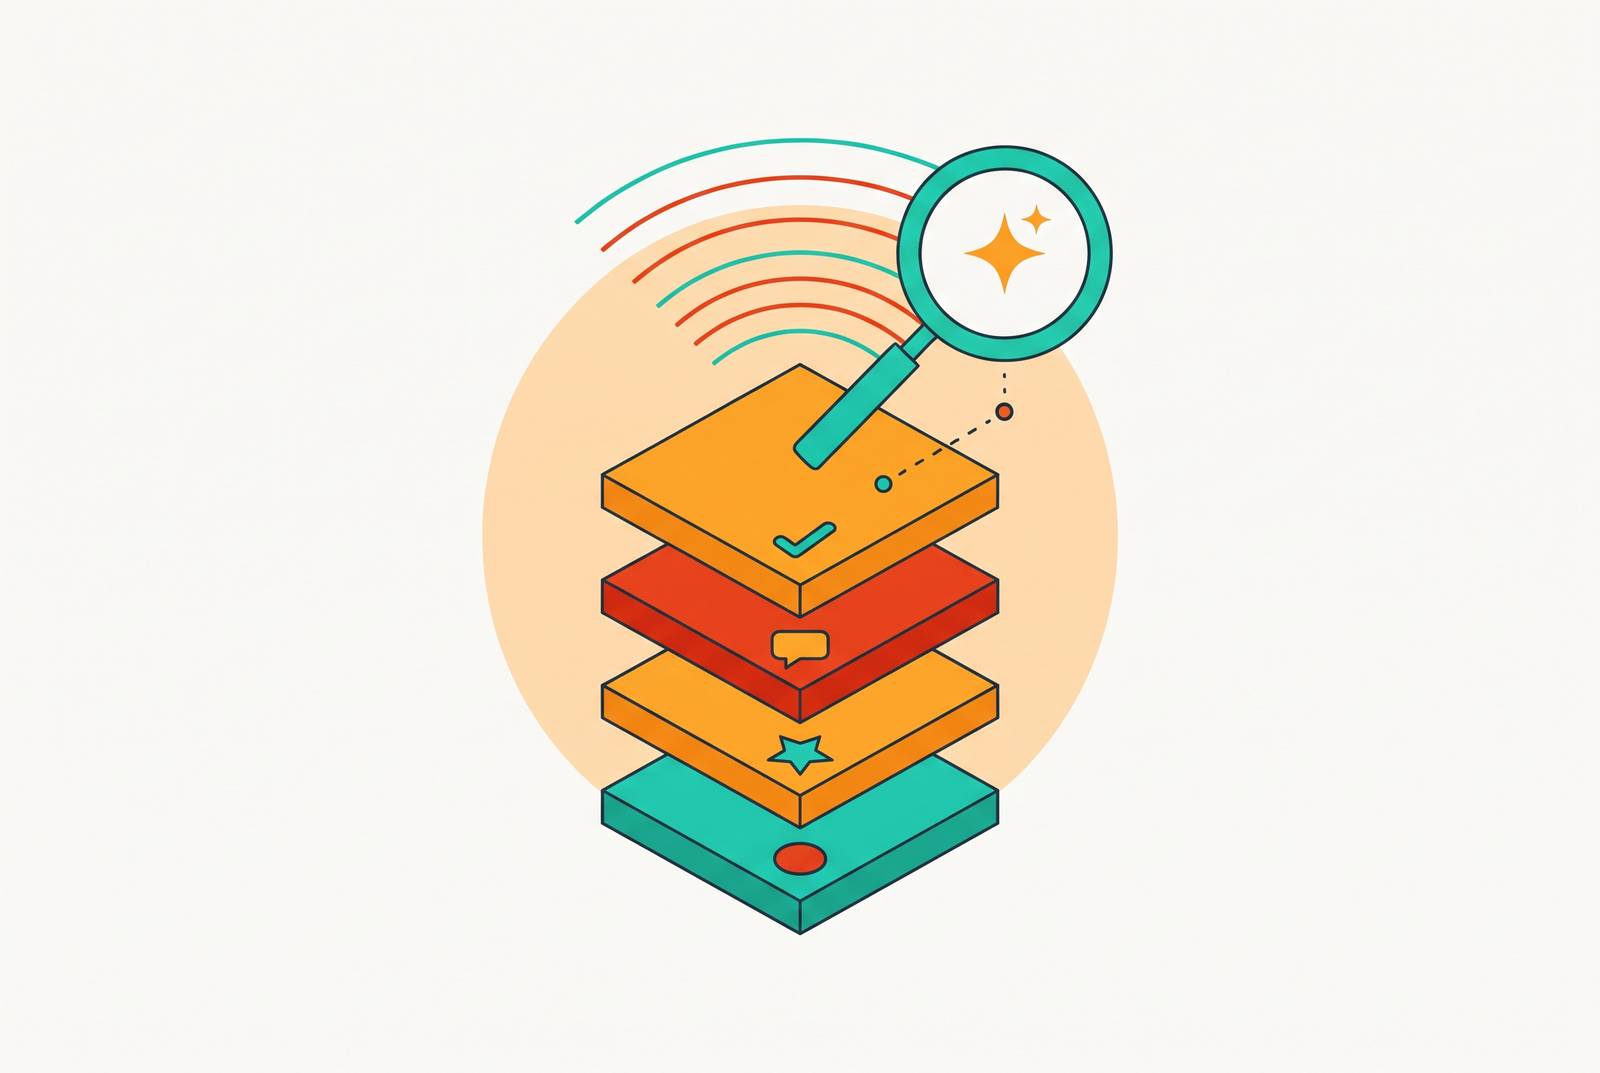
A brand signal stack is the structured set of cross-surface signals that makes a brand legible, trustworthy, and recommendable to AI systems. AYSA’s framework gives it three jobs, which are Found, Understood, and Chosen. Found means being in the discovery ecosystem, Understood means having information that agrees across that ecosystem, and Chosen means having enough third-party validation for a recommendation. Each job has a different failure mode. A brand may be excluded entirely, selected but misrepresented, or visible while a competitor gets the recommendation.
The next three sections develop those layers in turn. These jobs need to stay separate because being seen more cannot clear up who a brand is, and a clear identity cannot make others approve of it. Birdeye’s report places consistent, verifiable information at the center of AI visibility. That makes the stack shared operating work.
Being Found: building presence in the discovery ecosystem AI systems actually read
A brand’s website is only one part of the discovery ecosystem. AI systems also draw on community platforms, editorial articles, product roundups, comparison content, creator coverage, video, and review sites. Birdeye’s report notes that gaps in owned content increase reliance on third-party information.
Community content is especially relevant when buyers have not yet settled on a brand. Reddit citations skew toward category-level questions rather than brand-specific ones, making those discussions a discovery surface rather than merely a place to monitor existing customers. Comparisons and product roundups serve a related purpose because they place brands within a choice. Creator coverage and video add further sources from which an assistant can build its response. The old label “off-site” now sounds rather like calling the rest of the city “off-office.”
However, the value of that presence depends on which AI surface reads it. ChatGPT, Perplexity, and Google draw on different source pools, so visibility on one platform does not establish visibility everywhere. Distribution must therefore follow retrieval. A surface’s relevance depends on whether it contributes to answers in the brand’s category. A large presence in the wrong corner of the web can still leave an assistant with little useful evidence.
Being Understood: eliminating the conflicting signals that make AI systems distrust your brand
A website may describe one pricing model while reviews describe another, directories may assign different categories, and listings may contradict the claimed service area. AI systems build their view from all those signals together. The result can make a widely visible brand unsafe to recommend. Consistency is therefore trust infrastructure.
Birdeye’s report says that core trust signals include clear, structured information that is easy to extract and data that is complete and agrees across sources. For a multi-location business, each location has to meet those needs. A mismatch between a location page and a listing is not just an inconvenience for a customer seeking directions. It weakens the coherent picture on which a citation depends. A strong corporate website does not cancel out contradictory local information.
Schema markup and structured data help AI engines verify and reuse brand information, while plain language reduces ambiguity about what the business actually offers. Goodfirms’ 2026 SEO survey found that clear language remains far from universal among brands despite its value for AI citation. AYSA’s local-clinic example makes the consequence concrete. Strong traditional rankings can coexist with missing “best clinic” recommendations when reviews, mentions, and messaging fail to form a coherent account.
Being Chosen: the authority and trust signals that determine who AI recommends when brands are equally present
Once two brands are both findable and understandable, authority gives the assistant evidence for preferring one. AYSA’s playbook identifies editorial mentions, expert commentary, reputable comparisons, and strong review patterns as outside validation. Credibility cannot be self-claimed into existence.
That distinction appears in the language of the answer. A brand described as “the industry standard” or “widely recognized” occupies a different position from a “growing alternative” that is “gaining traction.” Both may receive a mention, but they do not receive the same endorsement. Specific differentiators, use cases, and social proof give an assistant grounds for a more confident description.
Human expertise also belongs in this trust layer. Goodfirms’ survey found that 100% of respondents expected E-E-A-T to become more important, its only unanimous finding. That agreement signals the weight marketers place on demonstrated experience and expertise, rather than proving how any particular assistant makes its selection. Authority also tends to compound once AI systems establish a brand as a leader. Yet that persistence is not a guarantee that the brand will appear in every subsequent answer.
Why brand signals are volatile by default and must be monitored continuously across multiple AI surfaces
AI visibility is not a position that stays won. Answers can change from one run to the next, and different engines draw on different sets of sources. A brand that appears prominently on one surface may be absent on another. Earning both a brand mention and a direct citation is associated with more consistent reappearance, but the two signals are not interchangeable. Being named is not the same as being used as a source.
This variability changes the operating requirement from building a stack to running one. Teams must monitor several AI surfaces because one favorable response gives no guarantee that the brand will stay relevant. Keeping information fresh also takes more than an annual audit. AYSA argues that teams shipping changes weekly will outpace those updating only quarterly. A quarterly refresh can be a minimum maintenance commitment without being an adequate response to every new gap.
The practical consequence is a standing feedback loop. Teams need to see where a brand disappears, where its description changes, and which sources support the answer. Otherwise, a new review pattern or a conflicting description can sit outside the website team’s field of view. The stack has no ceremonial finish line. It keeps working as long as the organization keeps the evidence behind it up to date and in agreement.
How do you measure whether AI assistants represent your brand accurately alongside traditional reputation metrics?
Rankings, click-through rate, and organic traffic describe only part of AI-era visibility. An assistant can put a brand in front of a potential buyer without sending that buyer to the website. AYSA and Birdeye both see being in an answer as a brand impression that has value for the business even when no one clicks. Measurement has not caught up with that shift. Goodfirms’ survey found that only 14% of marketers track AI/LLM citation visibility despite widespread strategic interest in AI optimization.
Citation frequency is a starting point for measuring share of voice. It asks how often the brand appears as a cited source when assistants answer relevant category questions. Mention frequency should be recorded separately because a name can appear without a direct citation. Mention order then shows where the brand sits within an answer and how stable that position is across repeated runs. None of these measures, by itself, establishes accurate representation.
Accuracy requires looking at what the answer says. Category, use case, pricing, geography, and service descriptions reveal whether the assistant has understood the brand correctly. Depth of description distinguishes a useful explanation from a passing reference. Authority framing shows whether the words cast the brand as a leader or an emerging alternative, while comparative positioning shows how it fares next to its competitors. These measures turn “the assistant mentioned the brand” into something more useful than a digital participation trophy.
Buyers choosing a perception intelligence platform need to distinguish between tracking where a brand appears and checking how it is described. Relevant criteria include coverage across AI surfaces, repeated-query tracking, separate mention and citation measures, description accuracy, and competitor comparisons. Traditional reputation measures still show what people think, through review patterns and what they say in public. AI-answer measures show how assistants synthesize those inputs, which may not match how people describe the brand directly. A useful comparison keeps those views distinct.
Assembling the stack in practice: the sequenced actions that build each signal layer
The build sequence starts with entity clarity, even though discovery is the first job in the conceptual framework. Distributing inconsistent information only gives the contradiction a larger audience. A team building the stack should first align naming, category, geography, service descriptions, and pricing across owned surfaces. Sequential headings, schema markup, and plain language then make those facts easier for AI systems to extract and reuse.
Comprehensive pages can explain what the offering is, who uses it, how to choose, and what it costs within a single URL. Quarterly content refreshes are the minimum cadence. Commercial and comparison pages need fresher windows, while the wider operating rhythm should allow faster changes when monitoring exposes a gap.
With the foundation in place, the next step is off-site presence. Priorities should reflect the sources each engine draws on, including YouTube for Google AI visibility, Reddit and community Q&A for Perplexity, and Wikipedia and editorial sources for ChatGPT. These priorities sit within each engine’s broader source pool. When editors include brands in roundups and comparison content, assistants have more evidence to draw on when choosing. Review management belongs in the same effort because review patterns help build the trust layer as well as showing how the business serves its customers.
Authority-building follows distribution, using specific differentiators, use cases, expert commentary, and social proof to support confident recommendations. The aim is justified leader language. Teams should pursue both brand mentions and direct citations, then run target category queries regularly across ChatGPT, Gemini, and Perplexity. Those runs should track depth, accuracy, authority framing, and comparative positioning as well as presence. The resulting gaps become prioritized content and distribution briefs, so the stack develops from evidence rather than from whichever dashboard happens to look green.