First-Party Data Collection Architecture for Personalization Pipelines
Building personalization on fragile analytics architecture creates compliance and attribution risk.
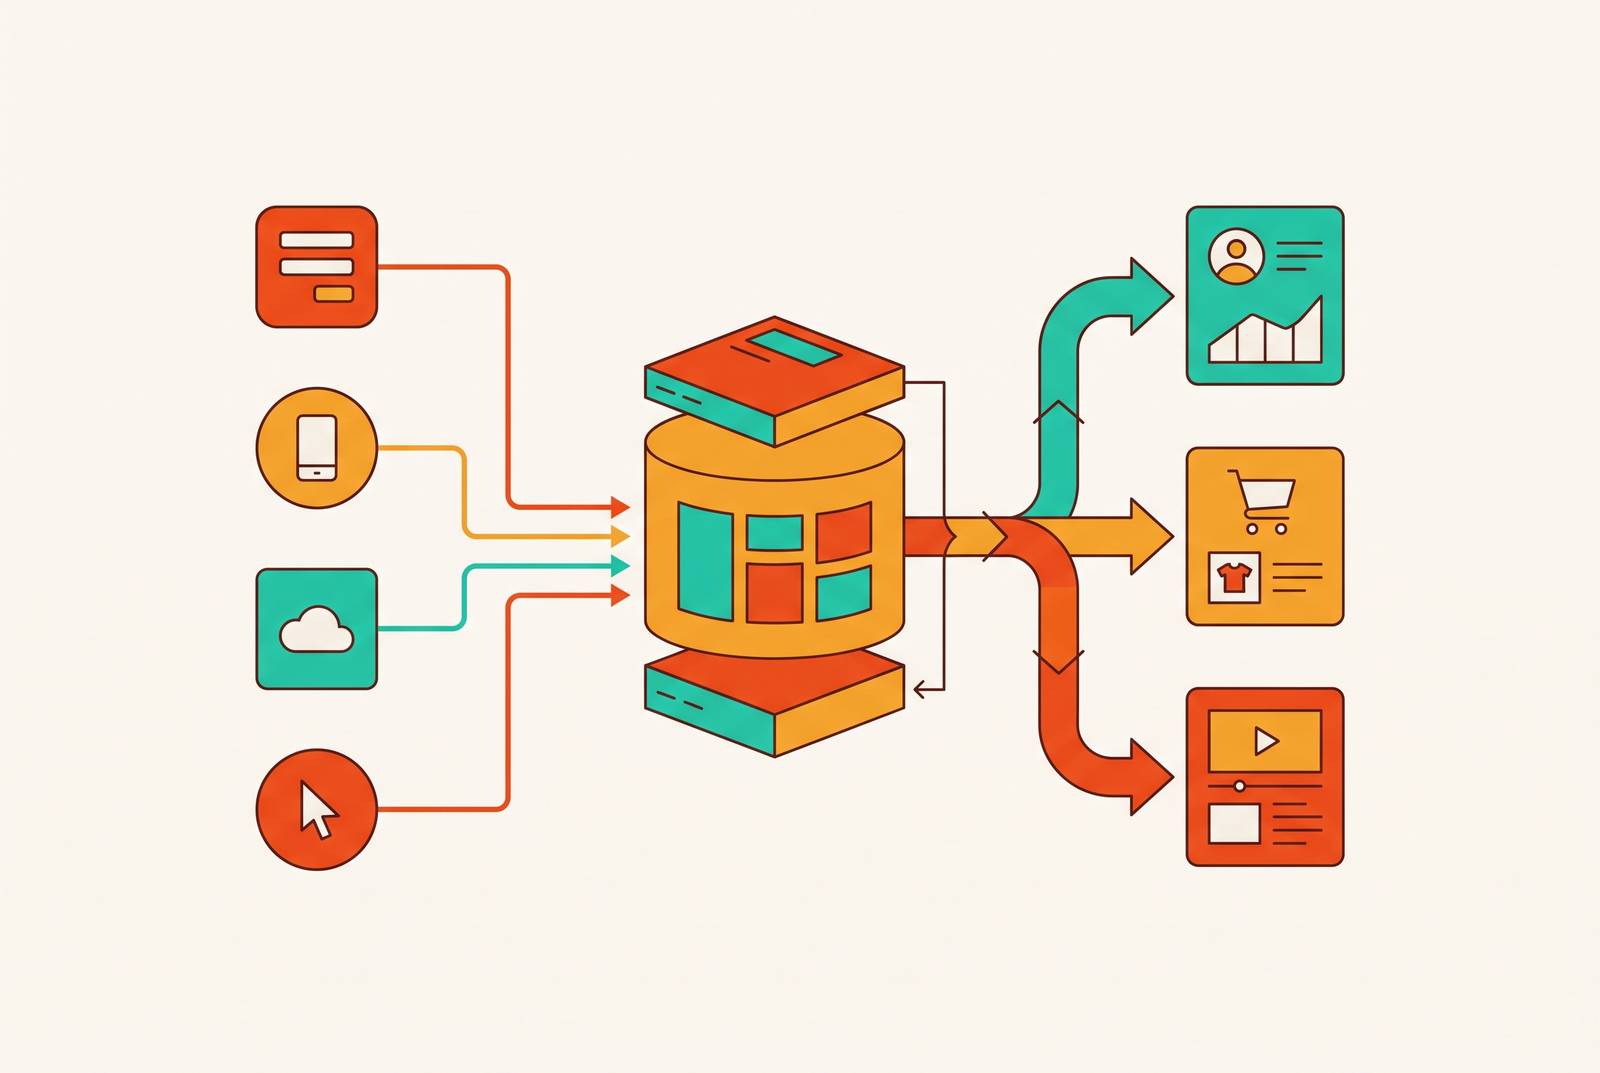
First-party data collection architecture for personalization pipelines is an engineering decision. Its durability depends on separating collection, governance, and activation, with consent, server-side infrastructure, and AI-readiness designed into the foundation. Personalization is the outcome of that architecture.
Why first-party data architecture is an engineering problem, not a marketing one
A team can spend years tuning an analytics setup and still see it break under a browser update and a regulatory flag. The browser change interrupts collection, while the audit exposes transfers the team cannot explain. Neither failure begins in a campaign. Both begin in an architecture that lets an analytics vendor determine how events are captured, governed, and used. Better reporting cannot repair that structural dependence.
Cookie deprecation, tightening privacy regulation, and customer expectations about tracking are closing off the technical and legal space for third-party collection. Privacy Sandbox adoption remains well under one in twenty major ad platforms, leaving no credible fallback at that scale. Marketers can define the information they need, but engineers must make its collection lawful, scalable, and usable by AI. Those properties must exist before a campaign depends on them.
What the GA4-centric trap looks like and why it collapses
The GA4-centric trap begins when event tags, consent logic, and data structure are all shaped around what GA4 needs. The setup may still produce reports the team can use, but beneath them it has no governed event stream that can move to another destination. Collection and reporting have become the same system. As a result, a change to the destination can require changes to the schema, consent handling, and routing that feed it.
That coupling exposes three distinct weaknesses. Browser restrictions and ad blockers target third-party scripts, so a vendor-managed pixel cannot provide a dependable collection boundary. A regulatory audit can then reveal external data transfers that the team neither designed nor can account for. Meanwhile, downstream ad channels have attribution gaps because the data they receive comes from a collection layer built for reporting. A dashboard can still serve reporting needs even when the systems beneath it are too fragile to support broader personalization.
The three-layer model: collection, governance, and activation as distinct engineering concerns
The correction is to collect events once, govern them once, and route the clean stream to the destinations that need it. Collection, governance, and activation are independent engineering domains. Each has a single job and its own failure modes. Their boundaries should allow a destination or component to change without cascading breakage through the pipeline. GA4 can receive that stream without setting its rules.
Collection is the point where data enters the system. A single lightweight tag or SDK under an owned domain sends events to an endpoint the organization controls, rather than letting third-party scripts fire independently. This layer handles behavioral, transactional, engagement, and declared data, including pages viewed, purchases, email opens, and stated preferences. Zero-party data enters here too, through deliberate disclosures such as surveys and preference forms. Its directness gives it greater consent clarity than information inferred from behavior.
Governance filters, shapes, and attaches consent state to those events before routing them. Its responsibility is to make each record usable for an authorized purpose. Activation then consumes the governed stream for personalization, segmentation, and prediction. Customer Match, lookalike audiences, and conversion API integrations belong in this final layer. None can make up for events or permission missing upstream.
Consent as a structural requirement, not a UI element
Consent belongs in the data model because every downstream system needs to know which uses a record permits. Even without regulatory pressure, that design makes the pipeline auditable and gives model training a traceable basis. A boolean flag cannot carry enough information. The record must include when consent was given, which privacy policy version applied, and which processing purposes it covered. A cookie banner is only the interface through which that state begins.
The Consent Management Platform must feed consent states into the pipeline in real time. Before an analytics SDK sends an event containing personal data, it must check that state. The CDP or data warehouse must preserve the consent basis with the record, while training pipelines filter records before building models. Activation systems must do their own permission check before they personalize content. Permission for analytics is not automatically permission for marketing, so authorization must remain attached to purpose.
That same architecture must support preference updates and immediate opt-outs across systems. Under GDPR, consent withdrawal takes effect immediately, while erasure must complete within one calendar month, extendable to three months. CCPA allows 45 days, extendable to 90 days. These are distinct obligations, so a deletion deadline is not permission to continue consent-dependent processing. The pipeline must be designed for the strictest applicable jurisdiction.
Data minimization adds a further constraint at collection. The SDK must collect only what the consent disclosure explicitly describes, because broader capture creates downstream liability. CCPA, as amended by the CPRA, establishes direct service provider liability for handling data beyond documented instructions. Consent engineering therefore extends from the collection interface through records, destinations, and the contracts governing their use.
Why server-side infrastructure is now the default, not the advanced option
These consent requirements make server-side infrastructure a foundation. Independent third-party scripts run their own logic outside the routing path that governance controls. That makes it unreliable to enforce a consent check before a vendor pixel sends data to an external server. Browser restrictions and ad blockers introduce a separate weakness by interrupting those scripts. Neither an analytics report nor an activation model can bring back events that never reached the pipeline.
An owned server-side endpoint establishes a boundary before data leaves the environment. Events arrive there before routing, allowing the server to verify consent before forwarding them. The organization also defines the event schema independently of any analytics tool. Adding or replacing a destination therefore does not require rebuilding collection around that destination’s requirements. Conversion API integrations can use this foundation to forward permitted events to ad platforms.
Identity resolution follows the same principle of reducing cookie dependence. Authenticated sessions, server-side IDs, and deterministic email-to-CRM matching support cross-channel messaging without relying on cookies, subject to the applicable consent basis. This architecture is more complex and slower to ship than a set of vendor-managed scripts. However, the simpler launch accumulates technical debt through consent violations, attribution gaps, and vendor lock-in. The engineering choice concerns where that complexity is handled.
Data quality inside the pipeline: what degrades it and how governance prevents that
Control over collection does not automatically make first-party data reliable. An owned pipeline can still receive invalid inputs, event names that do not match, and duplicate records. Quality must therefore be enforced at ingestion. Form validation checks the formats of email and phone numbers before they are captured, while email verification checks the address that was submitted. Standardized formats and taxonomies make equivalent events from different channels produce compatible records.
Governance maintains that consistency after ingestion. Regular cleaning and deduplication prevent unified profiles from accumulating records that distort segmentation and model training. Defined ownership and stewardship make clear who is responsible for each flow and how its data may be used. Documented systems of record and transformations then let the team trace where data entered, how it changed, and where it went. That traceability serves both incident diagnosis and regulatory audit.
Without these controls, errors compound as historical records accumulate. A model trained on duplicates or inconsistent events learns from a skewed picture of customer behavior. A model trained on improperly consented records has an additional defect, because its training basis is not legally defensible. Quality and consent are therefore complementary governance requirements. One establishes whether a record is dependable, while the other establishes whether it may be used.
How the activation layer connects governed data to personalization, segmentation, and prediction
A governed event stream makes personalization possible by providing profiles that fit together and have permission for that use. Dynamic website content depends on consistent behavioral collection and deduplication. Personalized email needs purchase and engagement records that have permission for marketing use. Product recommendations need browsing and buying patterns rather than only the subset of events that survived browser blocking. In each case, the outcome follows from an upstream property of the data.
The same foundation supports segmentation across behavioral, lifecycle, engagement, and product-affinity dimensions. Frequent buyers and lapsed customers require reliable purchase histories, while new subscribers and at-risk customers require a coherent view of lifecycle state. Email opens and content downloads show engagement, and interests in categories help place customers in product-affinity segments. Linking those sources avoids the limitations of parallel, unconnected pipelines. The activation layer can then use a unified profile instead of reconciling conflicting fragments during a campaign.
Prediction extends that benefit across historical records. Churn prediction, next-purchase timing, lifetime value forecasting, and lead scoring require data that was governed when collected. Customized landing pages and product recommendations use those signals to decide what customers see. Conversion API integrations send the same governed stream into paid media. Activation delivers the payoff precisely because it no longer has to compensate for defects in collection or guess at permission.
AI-readiness as a structural requirement the pipeline must be designed for from the start
The value of governed data now extends beyond human-facing personalization. The same behavioral records can supply the raw material for original research and proprietary analysis that shape how AI systems represent an organization. That creates a feedback loop from customer data to content positioning and then to AI perception. A pipeline designed only for campaigns leaves this dimension outside its measurement boundary. AI-readiness must therefore cover both model inputs and the evidence the organization makes available through its outputs.
LLMs evaluate authority through training data frequency, citation patterns, entity consistency, and content structure clarity, alongside link graphs. Tugtekin’s AI Perception Index 2026 finds a substantial perception gap between dominant and emerging brands across GPT-4o and Claude Sonnet. It also finds significant, measurable cross-model perception drift for the same brand. Even a strong brand can be represented differently across AI systems.
Governed first-party data gives original research material that has not been recycled and can be analyzed and potentially cited. Producing that material requires clean records and permission to use them, while presenting it requires clear content structure and consistent entity information across platforms. Evident scores the algorithmic, AI, and human dimensions of how a business is perceived. Those scores provide a structured way to assess whether outputs reach AI systems and represent the organization correctly. This broadens how the pipeline is judged beyond campaign performance, while AI perception remains outside the collection layer.
Building the pipeline in the right order: what to do in which sequence and why sequence matters
Campaigns, recommendations, and segments justify budgets because their outputs are easy to see. Collection and governance tend to go unseen until they fail. Building activation first therefore creates pressure to use records before their quality and permissions are established. Retrofitting those properties later requires rebuilding the systems that assumed them.
Start with an audit of existing data flows and their consent basis. Establish what is collected, where it goes, and whether independent vendor pixels bypass governance. Then implement consent architecture that captures timestamp, policy version, and purpose, with real-time propagation downstream. Keep historical records without the proper consent basis out of model training, even if the smaller training set makes personalization less accurate for a while. Rebuilding analytics and collection to enforce consent is a multi-month engineering project.
Next, build server-side collection with an endpoint under an owned domain and define an event schema that does not depend on the destination. Apply validation, verification, and format standards at capture across owned channels, including website behavior, email engagement, SMS responses, mobile app activity, and point-of-sale. Then connect the stream to governance that preserves consent, cleans records, and deduplicates profiles. Document ownership, stewardship, and data flows, and establish deletion pipelines targeting sub-one-hour latency for consent revocation. That latency is an engineering target, while immediate withdrawal handling and statutory erasure deadlines remain requirements.
Only after that governed stream exists should segmentation, personalization, and predictive analytics be built on it. Preference centers, quizzes, and surveys can then add declared data with clear consent, while conversion API integrations extend activation to ad platforms. Measurement must precede optimization across these uses. Campaign performance alone cannot show whether the architecture produces models that are accurate, evidence that can be used, and an AI representation that holds together. The pipeline is ready to improve only when its outputs can be scored across the human, algorithmic, and AI dimensions that now evaluate a business.